

The gap between “I’ve heard about llm-d” and “I have llm-d running and can experiment with it” shouldn’t be large. And technically, it isn’t, the quick start really does take under 30 minutes if your cluster is ready. But most quickstarts leave you staring at a running system with no idea what you’ve just deployed or what to tune next.
This guide won’t do that to you. We’ll go through every step of the llm-d quickstart, and after each step, we’ll pause and explain what just happened. You’ll finish not just with a running system but with enough understanding of what’s running to actually use it intelligently.
Before you start: what “production-grade” means here

When this guide says “production-grade inference,” it means a few specific things. It means inference that uses intelligent routing rather than round-robin. It means a system with KV cache awareness, so requests are routed to nodes that have relevant cached computation. It means a system with disaggregated prefill and decode capability. And it means a system that runs on Kubernetes with proper resource management and observability.
This is in contrast to “run vLLM on a single GPU and put it behind nginx,” which is also a valid approach for small deployments but doesn’t have any of those properties at scale.
The system we’re building today has all of those properties, and it’s the foundation you’d expand from if you were moving toward a serious production deployment.
Prerequisites: what you need before running anything
A Kubernetes cluster with GPU nodes
llm-d runs on Kubernetes. You need at least one node with one or more GPUs accessible to Kubernetes via the NVIDIA GPU Operator or AMD ROCm device plugin. If you’re working locally, a single-node K8s cluster via Kind, k3s, or MicroK8s with GPU passthrough works for experimentation. For a real deployment, you need actual GPU hardware.
# Verify your cluster can see GPUs
kubectl get nodes -o custom-columns='NODE:.metadata.name,GPU:.status.capacity.nvidia\.com/gpu'
If the GPU column shows values greater than 0, you’re good. If it shows empty or errors, you need to install the GPU device plugin first.
Helm 3.x
Helm is Kubernetes’ package manager. llm-d ships as Helm charts. Install Helm if you don’t have it:
curl https://raw.githubusercontent.com/helm/helm/main/scripts/get-helm-3 | bash
helm version  # Should show v3.x.x
kubectl configured for your cluster
Your kubectl should be pointing at the right cluster and have sufficient permissions (cluster-admin for initial setup, or the specific RBAC roles if you’re in a restrictive environment).
Storage for model weights
The model you’ll serve needs to be accessible to your GPU pods. In a real setup, this is typically a shared PVC (Persistent Volume Claim) backed by NFS, Ceph, or cloud storage. For experimentation, you can pull directly from HuggingFace during pod startup, though this is slow and not recommended for production.
Step 1: Add the llm-d Helm repository
helm repo add llm-d https://llm-d.github.io/helm-charts
helm repo update
What just happened: Helm repositories are indices of packaged Kubernetes applications. Adding the llm-d repo tells Helm where to find llm-d’s charts, YAML definitions for all the Kubernetes resources (Deployments, Services, CRDs, RBAC roles) that llm-d needs. The update command fetches the latest index from that repository so Helm knows what versions are available.
Step 2: Create a namespace
kubectl create namespace llm-dWhat just happened: Namespaces in Kubernetes are isolation boundaries. All llm-d resources will live in this namespace, making it easy to inspect, manage, and delete everything related to llm-d without touching other workloads in your cluster.
Step 3: Create a minimal values file
Create a file called my-values.yaml. We’ll start with the minimal configuration for a single-model deployment:
# my-values.yaml — minimal llm-d deployment

# The model to serve
model:
  name: "meta-llama/Llama-3.1-8B-Instruct"
  # For a real deployment, use a PVC path:
  # source: /mnt/models/llama-3.1-8b
  # For quick experimentation (slow, not for production):
  huggingfaceHub: true
  huggingfaceToken: ""  # Set to your HF token if the model requires it

# How to serve it
serving:
  tensorParallelSize: 1    # Start with 1 GPU, adjust to your hardware
  maxModelLen: 4096        # Max context length we'll support
  enablePrefixCaching: true  # Turn on KV prefix caching

# The intelligent scheduler (the key differentiator vs vanilla vLLM)
scheduler:
  type: predicted-latency   # Use ML-predicted latency for routing
  cachePolicyType: approximate  # Start with approximate cache routing

# Resource requests for the vLLM pods
resources:
  gpu: 1
  memory: "64Gi"
  cpu: "8"

# How many replicas to start with
replicas: 2   # 2 replicas so the scheduler has something to route between
What just happened (nothing yet, but let’s explain this file): This values file controls almost everything about your deployment. The model section tells vLLM what to load. The serving section configures vLLM’s runtime behavior, tensor parallelism splits the model across GPUs, maxModelLen caps how long inputs can be (affects KV cache memory sizing). The scheduler section is what makes this different from a vanilla vLLM deployment, which means you’re explicitly choosing the intelligent scheduler over round-robin. The replicas: 2 is important; with only 1 replica, the scheduler is making routing decisions between a pool of 1, which isn’t meaningful. You need at least 2 to see intelligent routing in action.
Step 4: Install llm-d
helm install llm-d llm-d/llm-d \
  --namespace llm-d \
  --values my-values.yaml \
  --wait \
  --timeout 10m
What just happened: Helm reads your values file, renders the chart templates into Kubernetes resource manifests, and applies them to your cluster. The --wait flag tells Helm not to return until all the deployed resources are in a ready state. The --timeout 10m gives it up to 10 minutes, model loading from HuggingFace can take a while on the first run.
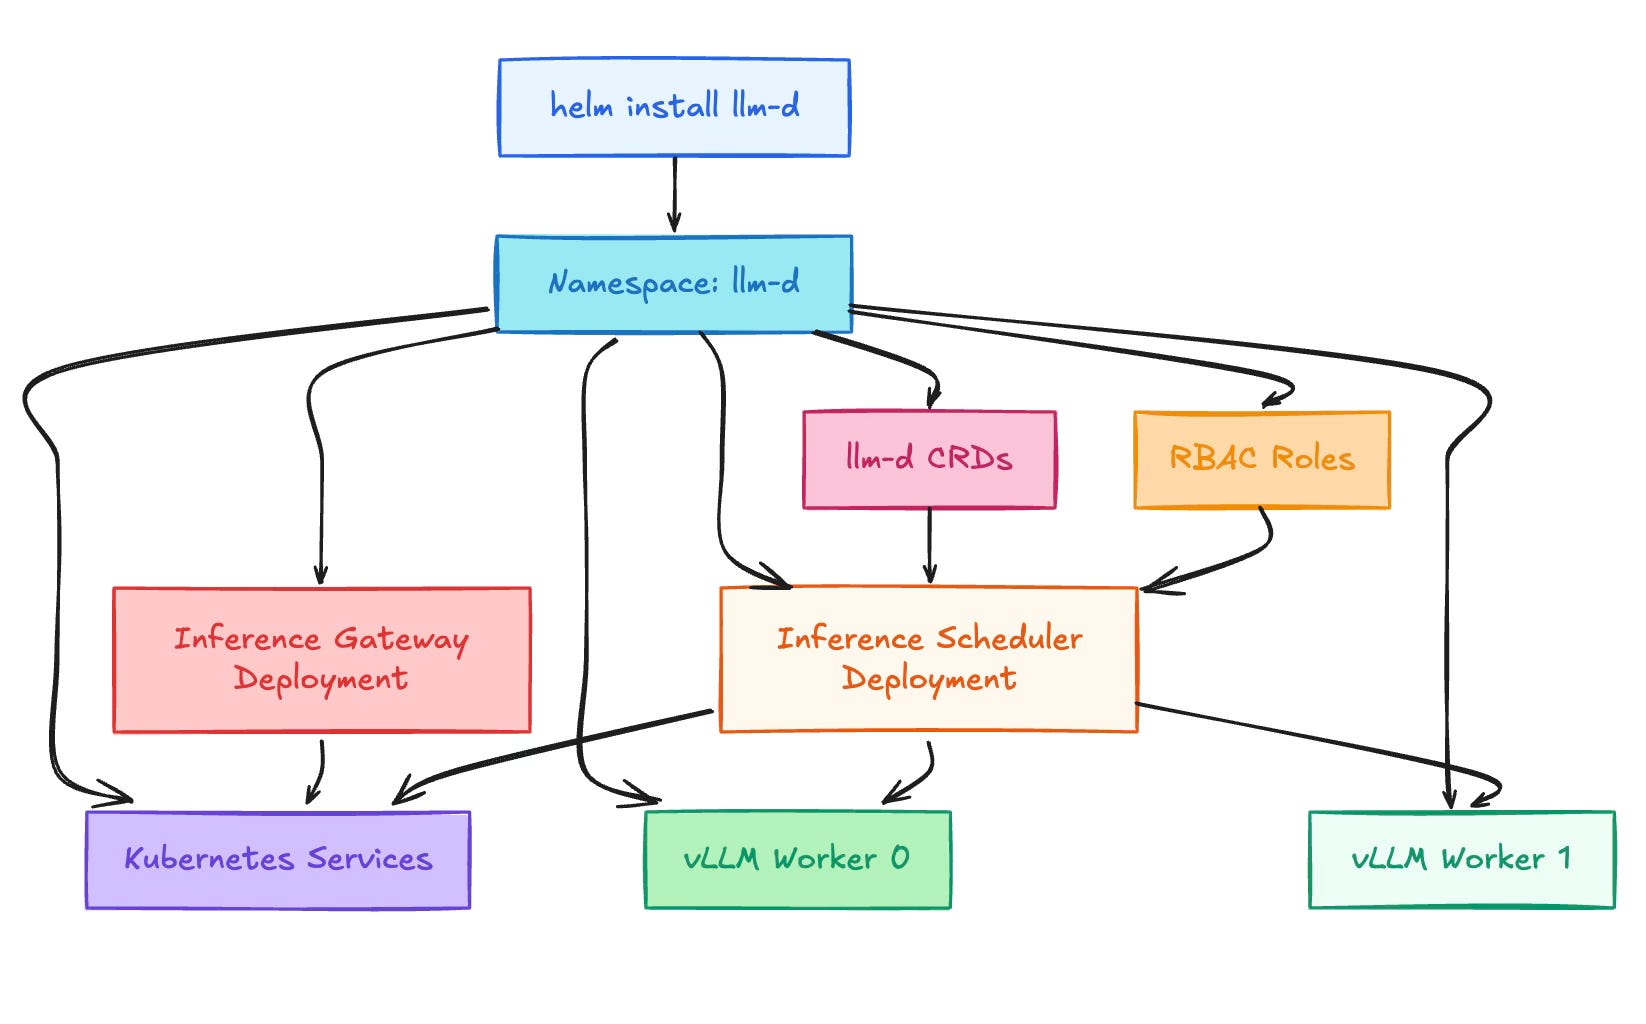
Under the hood, Helm is creating approximately these Kubernetes resources: a Deployment for the vLLM worker pods (one per replica), a Service that the scheduler uses to communicate with the workers, the Inference Scheduler as its own Deployment, the Inference Gateway as a Deployment with a LoadBalancer Service for external traffic, CRDs (Custom Resource Definitions) that define llm-d-specific objects like ModelService and InferenceSchedulerConfig, and RBAC roles allowing the scheduler to watch pod states.
# Check that everything came up
kubectl get pods -n llm-d
You should see something like:
NAME                                    READY   STATUS    RESTARTS   AGE
llm-d-gateway-7f9d8c-abc12             1/1     Running   0          4m
llm-d-scheduler-6b5f7d-xyz34          1/1     Running   0          4m
llm-d-worker-0                         1/1     Running   0          8m
llm-d-worker-1                         1/1     Running   0          8m
If you see Pending pods, the most common cause is insufficient GPU resources. Check kubectl describe pod llm-d-worker-0 -n llm-d for the specific reason.
Step 5: Verify the system is routing intelligently
Before sending real requests, let’s verify the scheduler is actually working. The scheduler exposes a metrics endpoint that shows routing decisions in real time:
# Port-forward the scheduler's metrics endpoint
kubectl port-forward -n llm-d svc/llm-d-scheduler 8080:8080 &

# Check scheduler status
curl http://localhost:8080/metrics | grep -E "cache_hit|routing|latency"
You should see metrics like llm_d_scheduler_cache_hit_total, llm_d_scheduler_routing_decisions_total, and per-worker metrics showing load distribution. If these metrics are present and incrementing after you send requests, the scheduler is working.
What just happened: Port-forwarding creates a tunnel between your local machine and a pod inside the cluster. The scheduler exports metrics in Prometheus format, which is why we can read them with a simple curl. The metrics you’re looking for confirm that (a) the scheduler is receiving routing requests, and (b) it’s making cache-aware decisions rather than just round-robining.
Step 6: Send your first request
Get the gateway’s external IP:
kubectl get svc -n llm-d llm-d-gateway
# Look for EXTERNAL-IP column
GATEWAY_IP=$(kubectl get svc -n llm-d llm-d-gateway -o jsonpath='{.status.loadBalancer.ingress[0].ip}')
Send a request using the OpenAI-compatible API:
curl http://${GATEWAY_IP}/v1/completions \
  -H "Content-Type: application/json" \
  -d '{
    "model": "meta-llama/Llama-3.1-8B-Instruct",
    "prompt": "Explain the difference between TCP and UDP in simple terms:",
    "max_tokens": 200,
    "stream": false
  }'
You should get a completion response. Send it a few more times, the scheduler is starting to build a picture of your request latency distribution.
What just happened: Your request hit the Inference Gateway, which validated it and forwarded it to the Inference Scheduler. The scheduler, on its first few requests, is in a cold-start mode, it doesn’t have enough traffic data to make well-calibrated latency predictions yet. It’s using queue depth as a fallback. After 50-100 requests, the online-trained latency predictor has enough data to start making meaningful predictions.
Step 7: Test cache-aware routing
Now send the same system prompt repeatedly to see prefix caching in action:
# A helper script to send 20 requests with the same long system prompt
SYSTEM_PROMPT="You are a helpful assistant specializing in distributed systems and Kubernetes. You have deep knowledge of container orchestration, service meshes, and cloud-native architectures. Always explain technical concepts clearly and provide concrete examples."

for i in {1..20}; do
  time curl -s http://${GATEWAY_IP}/v1/chat/completions \
    -H "Content-Type: application/json" \
    -d "{
      \"model\": \"meta-llama/Llama-3.1-8B-Instruct\",
      \"messages\": [
        {\"role\": \"system\", \"content\": \"${SYSTEM_PROMPT}\"},
        {\"role\": \"user\", \"content\": \"Question ${i}: What is a Kubernetes pod?\"}
      ],
      \"max_tokens\": 100
    }" > /dev/null
done
Now check the cache hit metrics:
curl -s http://localhost:8080/metrics | grep cache_hitWhat just happened: The first few requests in this loop had a cold cache, the system prompt’s KV blocks weren’t cached yet. By request 3-4, the system prompt’s blocks should be cached on whichever worker first processed a request with that prompt. The scheduler, recognizing the common prefix, should be routing subsequent requests to that worker. Your Time to First Token should be noticeably shorter for requests 5+ compared to request 1.
Step 8: Check the latency breakdown
Enable detailed latency metrics to see the prefill/decode breakdown:
# The vLLM workers also expose metrics
kubectl port-forward -n llm-d pod/llm-d-worker-0 8000:8000 &
curl http://localhost:8000/metrics | grep -E "ttft|time_per_output_token|e2e_request"
The key metrics to look at are:
vllm:time_to_first_token_seconds is your TTFT histogram. Look at the p50, p90, and p99 values. After your cache is warm (requests 5+), the p50 TTFT should be substantially lower than it was for the first request.
vllm:time_per_output_token_seconds is your TPOT (Time Per Output Token). This should be relatively stable, it’s driven by decode throughput, not prefill state. If this is high, your GPU memory bandwidth is the bottleneck.
vllm:gpu_cache_usage_perc tells you how full the KV cache is. If this is consistently above 90%, you’re running close to the eviction threshold, consider reducing maxModelLen or adding more replicas.
Step 9: Enable disaggregation (optional but educational)
If you have enough GPUs to run a prefill worker and a decode worker separately, you can enable disaggregation to see the TTFT improvements for long inputs:
# Update your values file
cat >> my-values.yaml << EOF

# Enable prefill/decode disaggregation
disaggregation:
  enabled: true
  prefillReplicas: 1    # 1 prefill worker
  decodeReplicas: 2     # 2 decode workers
  kvTransferBackend: tcp  # Use tcp for single-node; use uccl for multi-node
EOF

# Apply the update
helm upgrade llm-d llm-d/llm-d \
  --namespace llm-d \
  --values my-values.yaml
What just happened: You’ve split your workers into prefill specialists and decode specialists. Requests now flow through the prefill worker (which processes the input and generates the KV cache) and then the decode worker (which generates the output tokens). The KV cache is transferred between them via the configured transport backend.
Send a request with a long input to see the difference:
LONG_INPUT=$(python3 -c "print('word ' * 1000)")  # ~1000 token prompt
time curl -s http://${GATEWAY_IP}/v1/completions \
  -H "Content-Type: application/json" \
  -d "{\"model\": \"meta-llama/Llama-3.1-8B-Instruct\", \"prompt\": \"${LONG_INPUT} Summarize the above:\", \"max_tokens\": 100}"
Compare this TTFT to what you got before disaggregation. The difference will be most pronounced when your decode workers are under load, disaggregation prevents the prefill from blocking the decode stream.
What to tune first: the three highest-leverage knobs
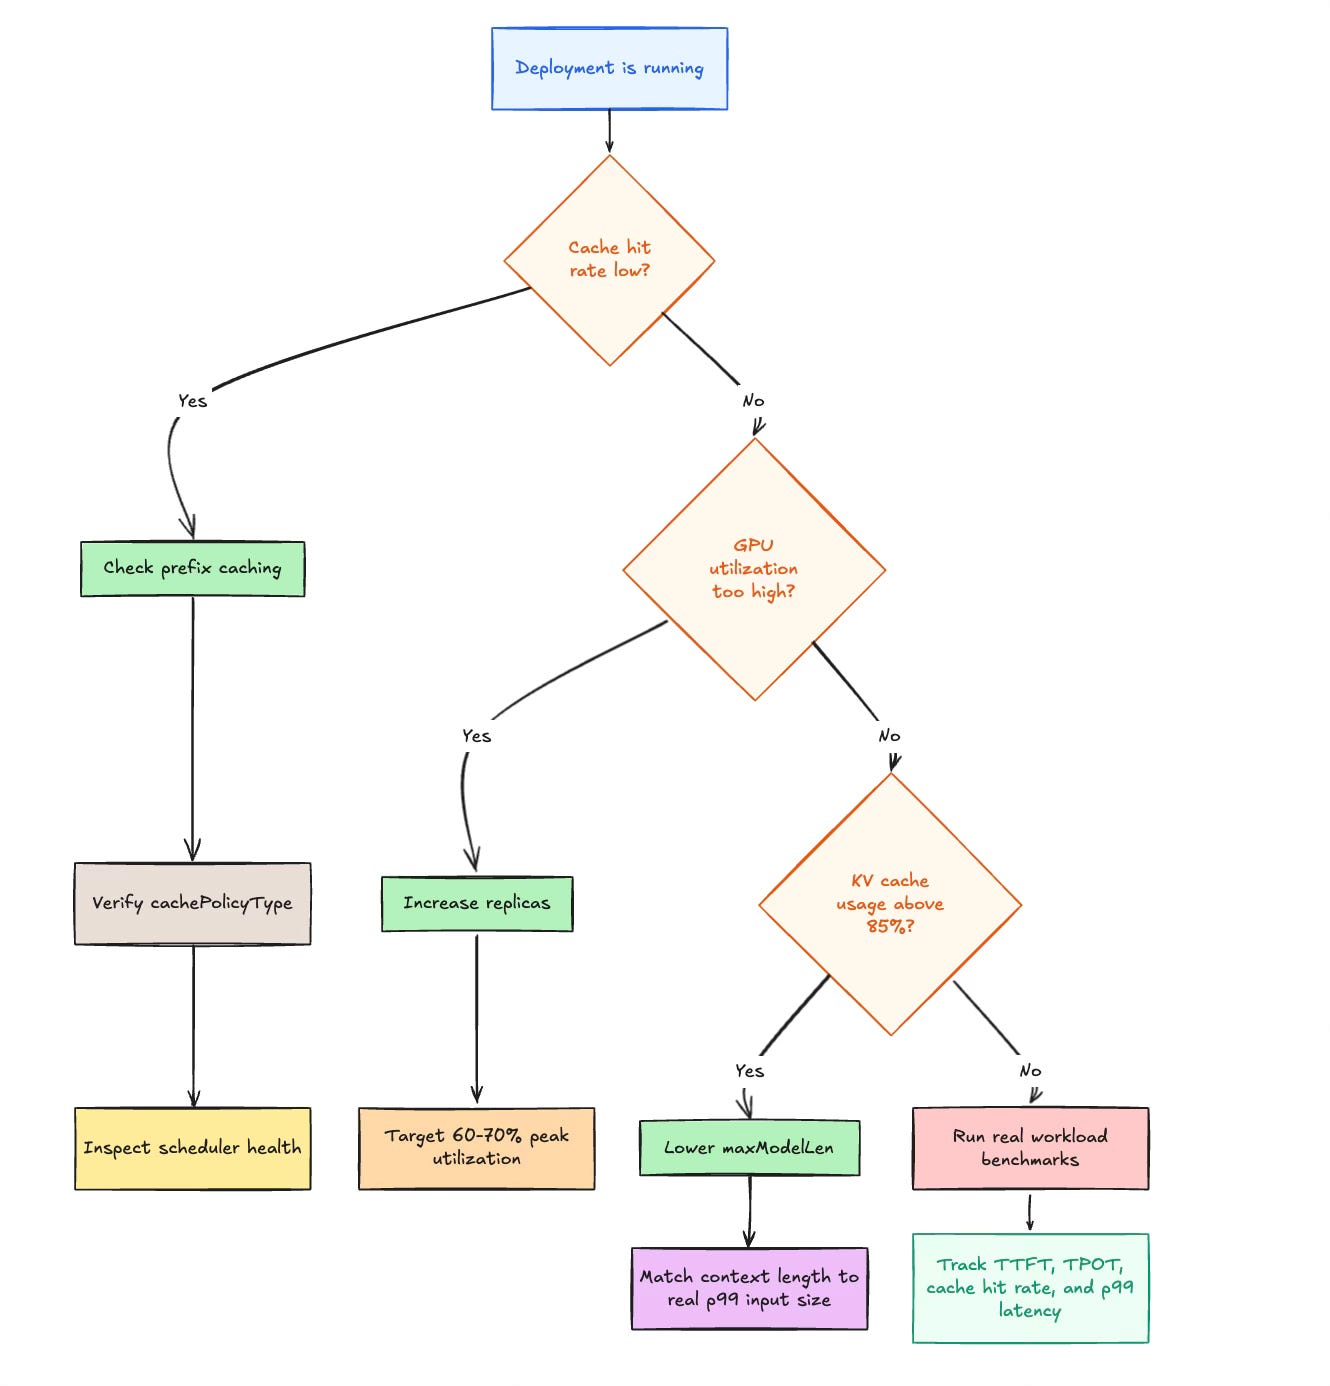
You now have a running, intelligent inference system. Here are the things worth tuning before you declare it production-ready.
Cache hit rate first. Run your real workload against the system for a few minutes and check llm_d_scheduler_cache_hit_total. If your hit rate is below 30% and you have workloads with shared system prompts, your routing might not be cache-aware yet, check that cachePolicyType: approximate is enabled and that the scheduler is healthy.
Replica count second. Two replicas gives you intelligent routing but not much headroom. For production traffic, you want enough replicas that any single replica being busy doesn’t degrade service. A rule of thumb: size for 60-70% peak GPU utilization per replica, with enough replicas that the system can absorb a 2x traffic spike without hitting 100% utilization.
maxModelLen third. This directly controls KV cache memory usage. A larger maxModelLen supports longer inputs but consumes more GPU HBM per active request. If your GPU cache usage is consistently above 85%, lower maxModelLen to match what your actual requests need. Most chat applications never need more than 8,192 tokens; RAG applications might need 32,768. Don’t set it to 128k “just in case” if your p99 input length is 2,000 tokens.
The full picture of what you’ve deployed
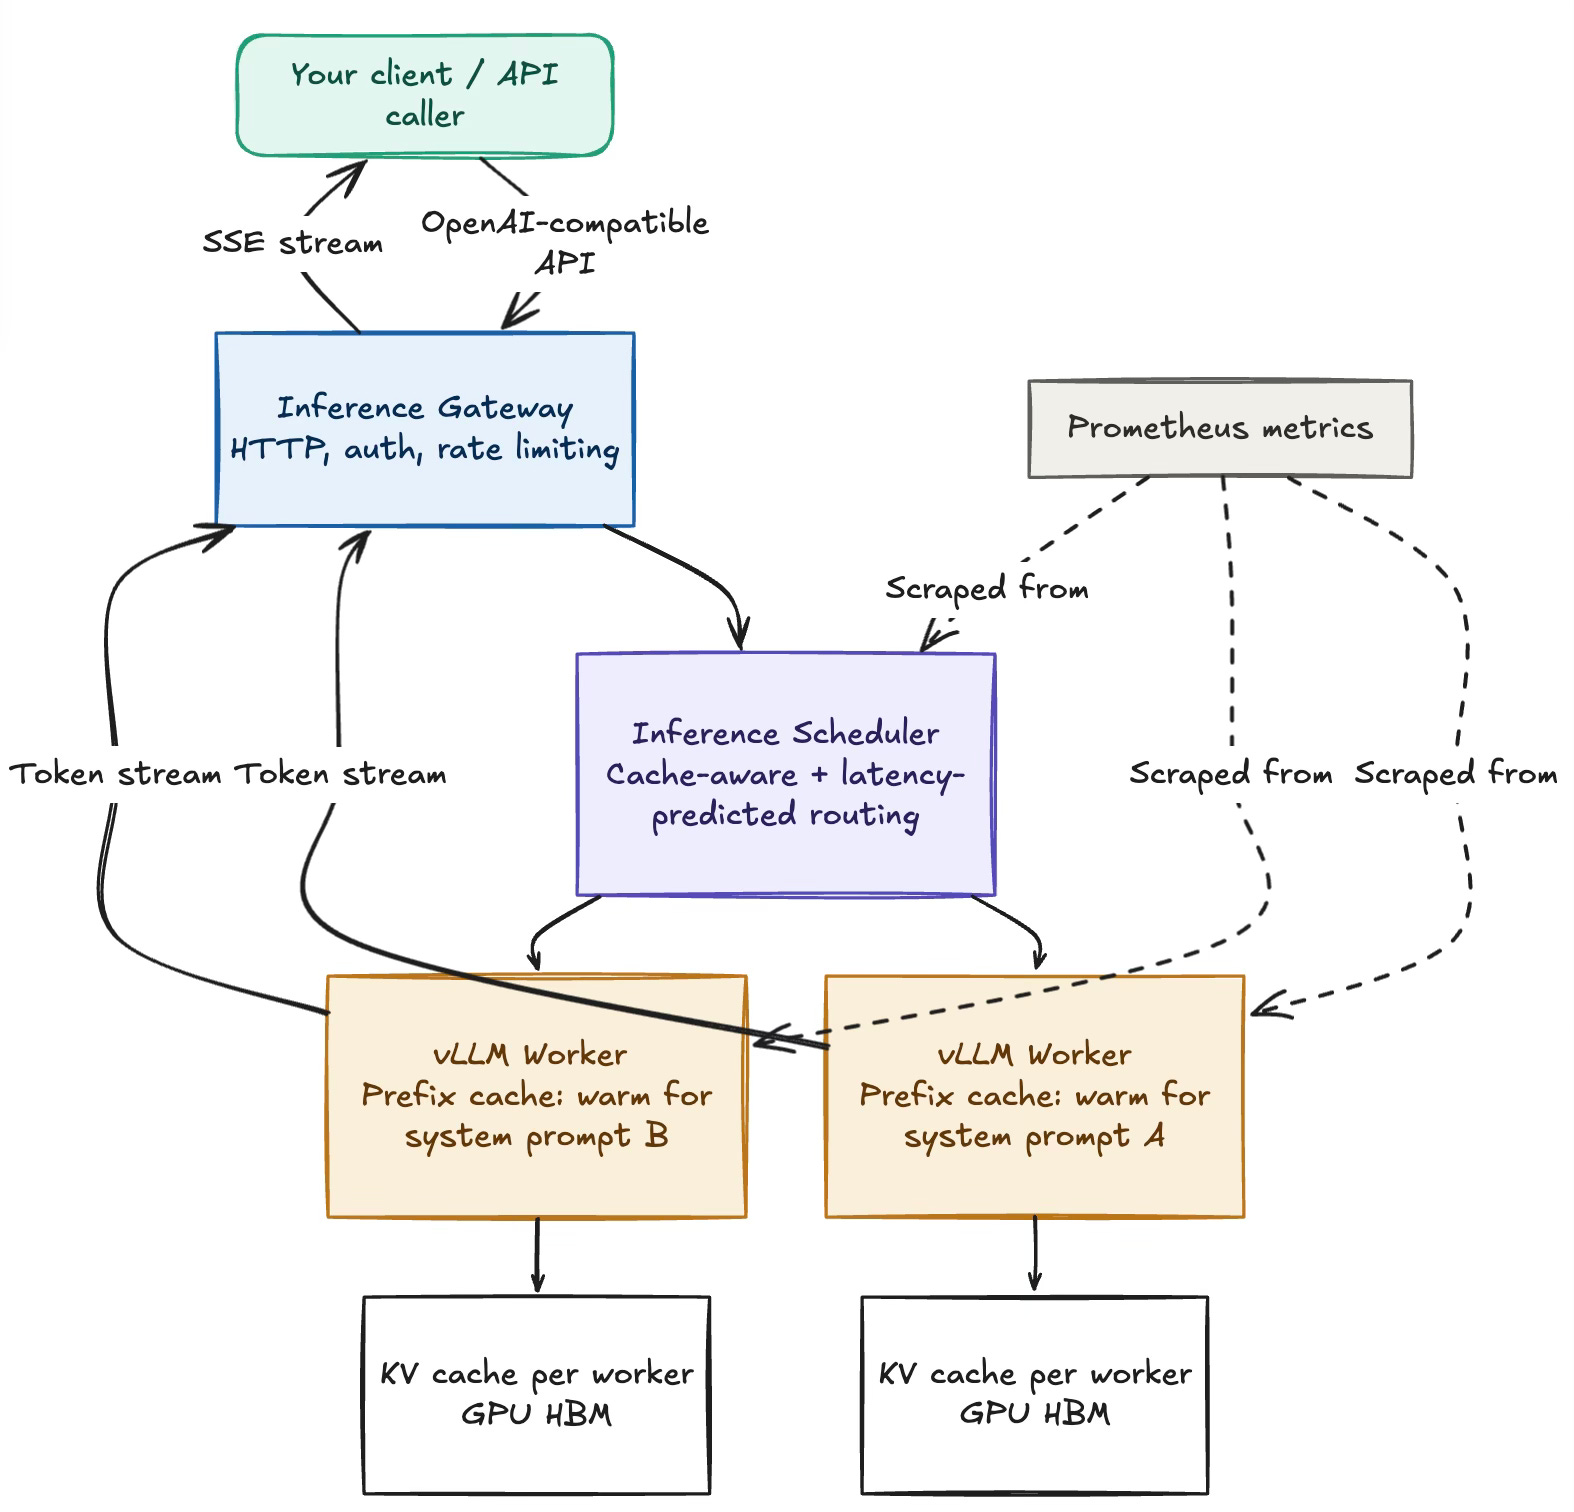
You deployed: an Inference Gateway that provides your OpenAI-compatible API endpoint; an Inference Scheduler that makes intelligent routing decisions based on predicted latency and KV cache state; two vLLM workers that actually run the model, each with their own GPU HBM KV cache; and a metrics pipeline that lets you observe all of it.
This is the foundation. From here, you can enable disaggregation, add the hierarchical KV offloading tiers, configure scale-to-zero autoscaling for cost efficiency on intermittent workloads, and add LoRA adapters for fine-tuned model variants, all without changing the fundamental architecture you’ve just deployed.